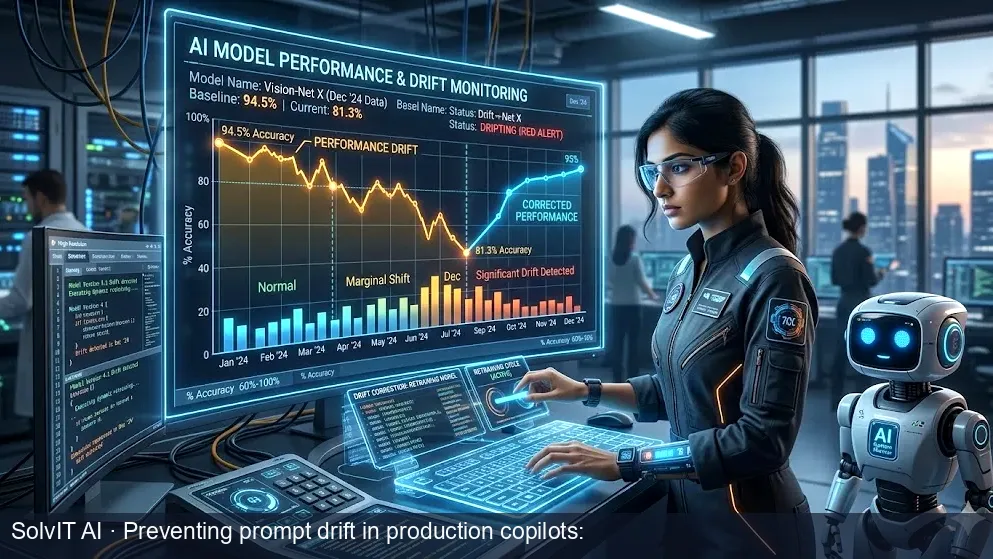
Your copilot shipped six months ago. It passed UAT, the pilot group loved it, and adoption is climbing. Then a support ticket lands: the assistant is giving a customer-facing answer that contradicts policy. You dig in. Nobody changed the model. Nobody changed the retrieval index. What changed was a prompt — edited in a console by someone on the platform team, three weeks ago, to fix an unrelated edge case.
That is prompt drift, and it is the most common cause of silent quality regression in enterprise copilots. It rarely announces itself. It shows up as a slow decay in answer quality, a spike in escalation volume, or a compliance incident that traces back to a one-line text change nobody reviewed.
For mid-market CTOs and technology leaders, the fix is not better prompts. It is treating prompts like code: versioned, tested, gated, and owned.
Why Preventing prompt drift in production copilots matters now
Three forces have converged to make this urgent.
Prompts are now production artifacts with production blast radius. A system prompt governs tone, refusal behavior, tool-calling rules, and data boundaries for every conversation. A single edit can change how your copilot handles PII, how it cites sources, or whether it escalates to a human. Yet in most organizations, that edit requires less approval than a CSS change.
Model and dependency churn is continuous. Foundation model providers ship updates on their own cadence. Retrieval pipelines get re-indexed. Tool schemas evolve. Even if your prompt text is frozen, the system around it is not — and prompt behavior is a function of the whole stack.
Evaluation is still immature in mid-market teams. Many organizations have a handful of "golden" test conversations in a spreadsheet, run manually before a release. That is not an eval harness. It is a vibe check with extra steps, and it will not catch a regression that only appears on the 4% of queries involving multi-turn tool use.
The cost of drift is not abstract. It is rework, incident response, lost user trust, and in regulated workflows, audit exposure.
Decision criteria and trade-offs
Before you build anything, decide what level of control your copilot actually needs. Not every assistant requires the same rigor.
- Customer-facing vs. internal. A copilot that drafts internal meeting summaries can tolerate more drift than one that answers customer billing questions or touches regulated data.
- Autonomy level. Read-only assistants that suggest answers are lower risk than agents that execute tool calls, write records, or send communications.
- Regulatory surface. If outputs are subject to audit, retention, or disclosure rules, your prompt change process is part of your control environment.
- Team topology. A single team owning the whole copilot can move fast with lightweight process. Multiple teams contributing prompts need explicit ownership and interfaces.
- Velocity tolerance. Aggressive iteration and strict regression gates are in tension. Resolve it by tiering: fast lanes for low-risk prompts, gated lanes for high-risk ones.
The trade-off is real: heavier governance slows iteration. The mistake is applying the same weight everywhere, or applying none at all.
Prompt versioning, eval harnesses, regression gates, and ownership for enterprise copilots
These four capabilities reinforce each other. Skip one and the others degrade.
Prompt versioning
Treat every prompt as a versioned artifact in source control, not a string in a database row or a vendor console.
- Store prompts in a repository alongside the application code that uses them.
- Use semantic versioning or content hashes so every production response can be traced to an exact prompt revision.
- Log the prompt version, model version, retrieval index version, and tool schema version with every inference. Without this, incident triage becomes archaeology.
- Require pull requests and review for prompt changes, with the same branch protections you apply to application code.
- Keep a changelog that explains why a prompt changed, not just what changed.
A useful discipline: if you cannot answer "which prompt produced this output?" for any conversation in the last 90 days, your versioning is not done.
Eval harnesses
An eval harness is a repeatable, automated suite that scores copilot behavior against expected outcomes. It is the only way to know whether a change helped or hurt.
Build it in layers:
- Golden set. 100–500 curated cases covering your highest-value and highest-risk workflows, including known failure modes. Every production incident should add a case.
- Scoring methods. Combine deterministic checks (does the output contain a required citation? does it call the right tool? does it refuse when it should?) with model-graded rubric scoring for subjective qualities like tone and completeness.
- Adversarial cases. Prompt injection attempts, out-of-scope requests, ambiguous inputs, and edge cases in multi-turn context.
- Operational metrics. Track escalation rate, deflection rate, user thumbs-down rate, and human override frequency as live signals that complement offline evals.
Run the harness on every prompt change, every model upgrade, and every retrieval pipeline change. Store results over time so you can see trends, not just pass/fail.
Regression gates
A regression gate blocks a change from reaching production when eval scores drop below a threshold.
- Define explicit thresholds per metric before you need them. "Overall quality must not drop more than 2 points, and refusal accuracy must not drop at all" is a gate. "It looked fine" is not.
- Gate on the metrics that map to business risk, not just aggregate scores. A copilot can improve on average while getting worse on the 5% of queries that matter most.
- Automate the gate in CI so it runs without a human remembering to run it.
- Allow documented overrides with named approvers. Gates that cannot be overridden get bypassed entirely; gates with a clear exception path get respected.
- Version your eval sets too. Changing the test to make the change pass is a failure mode worth naming out loud.
Ownership
Drift thrives in the gap between teams. Assign clear ownership:
- A named prompt owner for each copilot surface, accountable for quality and change review.
- An eval owner who maintains the harness, curates cases, and reports trends.
- A release owner who can approve overrides and owns the rollback decision.
- An executive sponsor who funds the eval work even when it produces no visible feature.
Ownership is not a RACI diagram that lives in a wiki. It is a name in the CODEOWNERS file and a person who gets paged when quality drops.
Implementation risks and mitigations
- Eval sets rot. Golden cases drift out of relevance as your product and user base change. Mitigate with a quarterly review and a standing rule that every incident adds a case.
- Model-graded evals inherit model bias. Use rubrics, multiple graders where feasible, and periodic human calibration on a sample.
- Over-gating kills velocity. Tier your gates by risk. Low-risk prompts get automated checks; high-risk prompts get full review.
- Shadow prompts and console edits. The most dangerous drift comes from changes made outside the pipeline. Restrict production prompt editing to the deployment path, and alert on out-of-band changes.
- Cost and latency of evals. Run full suites pre-release and sampled suites continuously. Budget for it explicitly.
- Attribution gaps. If you cannot correlate a quality drop to a specific change, your observability is incomplete. Instrument prompt, model, retrieval, and tool versions together.
Recommended next steps
- Audit your current state. Inventory every prompt in production, where it lives, who can edit it, and whether changes are reviewed. Most teams find at least one console-edited prompt nobody owns.
- Freeze and version. Move prompts into source control this sprint. Add version logging to your inference path.
- Build a minimum viable harness. Start with 50 golden cases covering your top workflows and known failures. Expand from there.
- Wire one gate. Pick your highest-risk copilot surface and add an automated regression gate to its deployment pipeline.
- Name owners. Assign prompt, eval, and release ownership in writing, with escalation paths.
- Review monthly. Track eval trends, incident-derived cases, and override frequency as standing agenda items.
Prompt drift is not a prompt problem. It is a release engineering problem, and it responds to the same discipline you already apply to code. The teams that get this right ship faster over time, because they can change prompts confidently instead of fearfully.
If you want a structured assessment of where your copilot's prompt governance stands today, book a free AI audit with SolvIT AI. We will map your current prompt lifecycle, identify drift exposure, and give you a prioritized plan for versioning, evals, gates, and ownership.